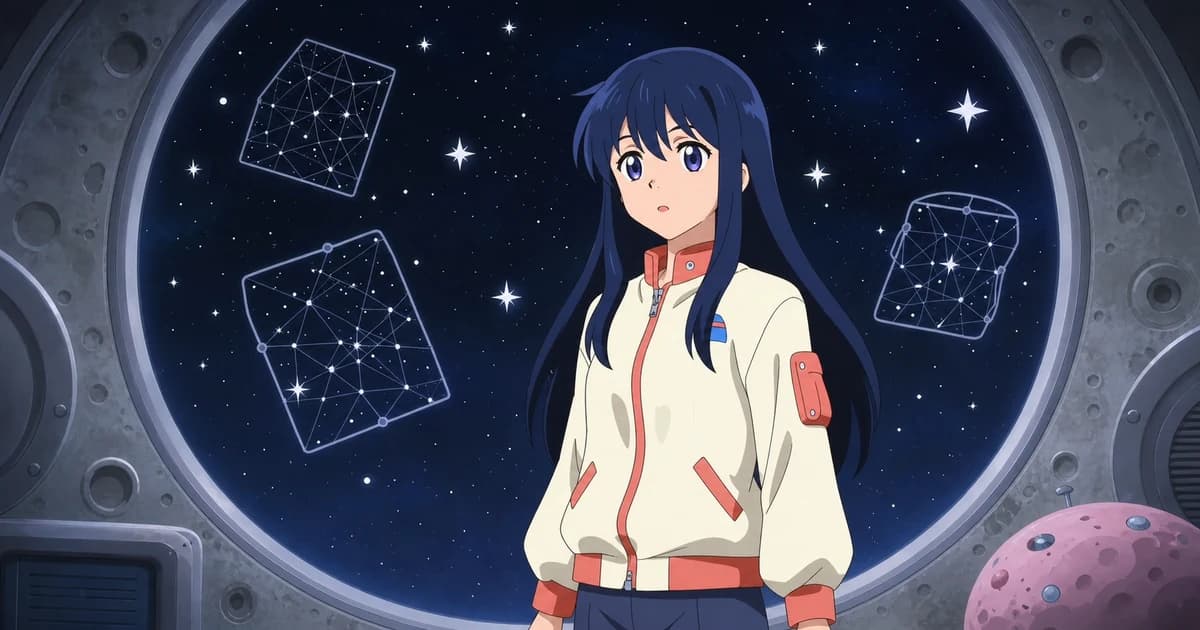
A consistent AI character is recognizable across new clothes, poses, locations, expressions, and lighting. The goal is not to reproduce one picture. It is to preserve identity while the shot changes.
There are four useful levels of control:
| Method | What it controls | Best use | Main limitation |
|---|---|---|---|
| Repeated identity prompt | Described traits | Early character exploration | Faces drift as scenes become complex |
| Fixed seed | A controlled comparison | Testing one prompt change | It is not a permanent identity |
| Reference image | Visual resemblance in one generation | An authorized one-off image | Pose, crop, and lighting can leak into the result |
| Character LoRA | A reusable learned identity | A recurring fictional character | Requires a clean dataset, compatible base model, and validation |
Start with prompts. Train a LoRA only when the character has become a repeatable asset.
What is a LoRA?
LoRA means Low-Rank Adaptation. The original LoRA paper freezes a pretrained model and learns a much smaller set of update matrices instead of changing every model weight.
In simplified form, the model keeps its original weight matrix W and applies a learned update:
W adapted = W + scale × (B × A)
The matrices A and B have a small rank, so the adapter has far fewer trainable parameters than the base model. In an image model, those updates can teach a denoiser or transformer a character identity, style, object, or visual concept. The Hugging Face Diffusers documentation describes LoRA as a lightweight adapter commonly loaded into a denoiser, text encoder, or both.
Three consequences matter in practice:
- A LoRA is not a complete image model. The adapter file, often a
.safetensorsfile, still needs the compatible base model. - The trigger word is a label, not the identity itself. The learned weights connect that token to patterns in the training set.
- More LoRA weight is not always better. A strong weight may preserve the face but flatten expressions, clothes, composition, and realism.
LoRA improves identity consistency. It does not replace prompt structure, pose control, composition, or art direction.
1. Choose the base model before the dataset
A character adapter is tied to the architecture and checkpoint family it was trained against. Training on one base and loading it into an incompatible pipeline may fail outright or produce weak, distorted results.
Elyvie separates two Z-Image paths:
- the free public generator uses Tongyi-MAI/Z-Image-Turbo for fast prompt exploration;
- the controlled character-training workflow uses the undistilled Tongyi-MAI/Z-Image base.
This is deliberate. The official Z-Image model card identifies the base model as suitable for LoRA training and lists Turbo as not fine-tunable. The base model also supports CFG, negative prompts, and a longer 28–50 step inference path, while Turbo is optimized for speed.
Do not train first and choose the production model later. Record the exact base model, revision, training tool, adapter format, and inference loader before collecting images.
Why an open-source, open-weight image model is a production requirement for Elyvie
A closed image API is useful when the question is “can this prompt make an attractive picture?” Elyvie has a harder question: “can this fictional person remain the same character for months while models, scenes, clothing, and product features evolve?”
That requires control over four separate artifacts:
- The base model that defines the visual prior.
- The LoRA adapter that carries the learned identity.
- The inference recipe: loader, scheduler, steps, CFG, seed, dimensions, negative prompt, and adapter weight.
- The evidence: dataset manifest, captions, checkpoints, and validation renders.
With a closed API, the provider can change the model behind a stable model name, remove a parameter, reject an adapter format, or discontinue fine-tuning. Even when every change is reasonable, the character’s face can drift and you may have no old checkpoint to reproduce the previous result.
An open-weight model changes the ownership boundary:
| Production need | Closed image API | Open-weight model |
|---|---|---|
| Train a custom identity adapter | Only if the provider exposes it | We control the trainer and target modules |
| Pin the exact base revision | Often abstracted or provider-managed | Model ID, revision, and files can be recorded |
| Load and A/B several LoRAs | Provider-dependent | Adapter IDs and weights are application state |
| Reproduce an old character render | Vulnerable to silent model changes | Old base, adapter, seed, and recipe can be retained |
| Move between GPU suppliers | Usually means changing APIs | The same container and weights can move |
| Set product safety policy | Provider policy plus our policy | Our policy and legal obligations remain our responsibility |
The official Z-Image repository and model card publish Z-Image under Apache 2.0. More importantly for this workflow, the undistilled base is explicitly fine-tunable while Turbo is not. The license, downloadable weights, and trainable architecture are three different checks; “open source” should never be used as a shortcut for skipping any of them.
This is why I treat open weights as a must for Elyvie’s recurring-character layer, not as a universal rule for every image prototype. A closed API can still be the fastest tool for mood boards or one-off images. Once identity becomes durable product data, I want the option to pin, train, inspect, migrate, and reproduce the complete stack.
Open weights also do not remove safety work. They move responsibility toward the operator. Elyvie still needs rights checks, fictional-adult boundaries, access control, private storage, deletion, and abuse prevention.
2. Write a one-page identity sheet
Keep the permanent part short:
- fictional adult age range;
- face shape and skin tone;
- eye color and eye shape;
- hair color, length, texture, and signature cut;
- two distinctive features;
- baseline body description;
- one signature accessory or color;
- three personality words that affect expression and posture.
Example:
Fictional adult woman, age 28, heart-shaped face, warm olive skin, amber almond-shaped eyes, silver jaw-length bob with blunt fringe, one small beauty mark beneath the left eye, translucent raincoat, observant, composed, quietly defiant.
Separate the identity into three layers:
| Layer | Examples | Rule |
|---|---|---|
| Immutable identity | Face shape, eye shape, skin tone, hairline, signature mark | Keep fixed |
| Controlled variation | Hair styling, makeup, accessories, wardrobe | Change deliberately |
| Shot-only information | Location, pose, lens, weather, lighting | Never place in the identity sheet |
If location and lighting are mixed into the identity block, the model can learn “this person always stands in this room” instead of learning the person.
3. Prove the identity with prompt-only tests
A reliable order is:
- medium and shot type;
- identity block;
- clothing changes;
- action and expression;
- setting;
- light and camera;
- quality and output constraints.
Generate three neutral portraits before building a dataset: front, left three-quarter, and right three-quarter. Use simple clothing and clean light. Check:
- eye color and distance;
- hair silhouette;
- face shape;
- signature detail;
- approximate apparent age.
If the neutral image is unstable, a cinematic scene will not fix it. Revise the identity block before adding complexity.
Use a fixed seed only to compare one prompt revision with another. It cannot guarantee identity after a major prompt, model, sampler, dimension, or LoRA change.
4. Select identity anchors, not just attractive images
An identity anchor is a reference that clearly shows who the character is. A good anchor has:
- one visible fictional adult;
- sharp eyes and unobstructed facial geometry;
- plausible skin texture without a heavy beauty filter;
- a consistent apparent age, hairline, eye color, and distinguishing features;
- enough difference in angle and expression to reveal the identity in three dimensions.
Reject anchors with motion blur, extreme lens distortion, covered eyes, multiple faces, inconsistent hairlines, conflicting ages, or nearly identical crops.
Elyvie’s current controlled workflow starts with 4–5 identity anchors and selects exactly four as dataset-generation references. This is enough to establish a direction, but it is not the final training set.
5. Build a dataset that teaches variation
The training set must answer two questions at once:
- What must remain the same?
- What is allowed to change?
Twenty close-up selfies answer only the first question. The resulting LoRA may reproduce one face angle while failing at full-body shots, motion, ordinary lighting, or new clothes.
Elyvie uses a 20-scene dataset template:
| Shot scale | Scenes | Why it is included |
|---|---|---|
| Close | 3 | Eyes, face shape, hairline, and small identity details |
| Half-body | 6 | Expression, posture, hands, clothing, and ordinary interaction |
| Full-body | 6 | Body proportion, movement, outfit changes, and distance |
| Environmental | 5 | Identity under smaller framing, mixed light, and real backgrounds |
The scenes vary indoor and outdoor locations, expressions, camera angles, daylight, practical light, wardrobe, and action. They deliberately avoid twenty copies of the same studio portrait.
Each candidate is checked for:
- exactly one face;
- identity score of at least 75/100;
- realism score of at least 70/100;
- safety approval;
- no exact duplicate of an already accepted image.
The current pipeline allows up to three candidate attempts per scene and requires at least 15 accepted images, with a maximum of 20, before training. Those thresholds are Elyvie implementation gates, not universal scientific constants. The principle is universal: reject bad evidence before it reaches the trainer.
6. Caption what changes and use a unique trigger word
A caption should identify the character token and describe variable content:
cylara_elyvie, fictional adult woman, waist-up, beige linen shirt, seated at an outdoor cafe, soft late-afternoon daylight, warm candid smile
Keep the token unique and pronounceable. Do not use a common word such as “woman,” “hero,” or “Anna” as the only trigger.
Caption the clothing, framing, action, expression, and setting because those should remain controllable. Avoid repeating temporary attributes as though they are permanent identity. If every caption says “red dress,” the adapter may bind the red dress to the person.
Elyvie derives a stable trigger in the form character_slug_elyvie and stores it with the LoRA ID, base-model identity, and selected training manifest.
Worked example: turn the moon-observatory image into a reusable character
The astronaut on this article’s cover is a useful example because the first image already contains a strong concept: an adult astronomer, midnight-blue hair, a cream flight jacket with coral details, and a circular lunar observatory. It is not yet a reusable character. It is one successful composition.
Suppose I decide to promote her into a recurring Elyvie character named Mira. I would not immediately train on the cover image. First I would write:
mira_observatory_elyvie, fictional adult woman, age 26, oval face, large violet almond-shaped eyes, straight midnight-blue hair below the chest with a soft side fringe, small straight nose, cream flight jacket with coral hardware, curious, measured, quietly brave.
The jacket is a controlled signature, not a permanent body part. The observatory is shot information, not identity.
Step A: create four identity anchors
| Anchor | Framing | What it must prove |
|---|---|---|
| A | Front close portrait, plain light | Eye spacing, face shape, fringe, apparent age |
| B | Left three-quarter portrait | Nose, cheek, jaw, and hair volume |
| C | Right three-quarter portrait | The opposite facial plane and asymmetry |
| D | Neutral full-body frame | Height impression, body proportion, and hair length |
I reject an anchor if it introduces a different eye color, shorter hair, a younger-looking face, or heavy anime distortion that is absent from the other three. Four agreeing anchors are better than eight contradictory ones.
Step B: deliberately break the original composition
The generated training scenes should prove that Mira is not “the woman inside the round observatory window.” I would include:
- a close portrait in ordinary window light, wearing a dark crew-neck top;
- a half-body bookstore scene with a knit jacket and a small smile;
- a full-body windy seaside scene in a practical coat;
- an environmental night-market frame under mixed neon light;
- one observatory scene that preserves the original story world without dominating the dataset.
This is the difference between identity training and image reconstruction. Nineteen observatory images plus one cafe image will teach the room.
Step C: caption the variables
Example captions:
mira_observatory_elyvie, fictional adult woman, close portrait, dark crew-neck top, public library, soft overhead and window light, attentive expression
mira_observatory_elyvie, fictional adult woman, full-body walking pose, light windbreaker, seaside promenade, bright cloudy daylight, subtle smile
mira_observatory_elyvie, fictional adult woman, environmental frame, cream flight jacket with coral details, circular lunar observatory, cool practical light, curious expression
The trigger is constant. Framing, clothes, location, light, and expression change. That separation tells the adapter what to preserve and what the prompt should continue to control.
Step D: validate with prompts the dataset never showed
I would hold these prompts out of training:
- Mira laughing in a black evening suit under warm restaurant light.
- Mira in a red raincoat, full-body, crossing a bright daytime street.
- Mira as a small figure in a wide desert landscape at sunset.
- Mira in the original observatory, but with a worried expression and no flight jacket.
If only prompt 4 works, the LoRA learned the observatory concept more strongly than the identity. If close-ups pass but prompt 3 fails, the dataset lacks scale variation. If the suit becomes a flight jacket, clothing is over-bound.
Step E: choose the weakest passing adapter weight
Here is an illustrative decision log, not a universal benchmark:
| Weight | Identity | Realism | Flexibility | Decision |
|---|---|---|---|---|
| 0.65 | 76 | 88 | Excellent | Pass, but identity is only just stable |
| 0.70 | 84 | 85 | Good | Activate |
| 0.75 | 90 | 78 | Clothing begins to repeat | Keep as fallback |
| 0.80 | 93 | 66 | Waxy face and frozen expression | Reject |
I would activate 0.70. The highest identity score loses because a production character must still act, change clothes, and survive different cameras. LoRA is an identity constraint, not a command to make every image resemble the training set.
7. Understand the training controls
Exact flags differ by trainer and model, but every useful training record should answer these questions:
| Control | What it changes | Failure signal |
|---|---|---|
| Base checkpoint | The visual knowledge receiving the adapter | Adapter will not load or identity is incoherent |
| Rank / dimension | Adapter capacity and file size | Too low misses identity; too high can memorize noise |
| Alpha / network scale | Effective strength during learning | Unstable or excessively strong adaptation |
| Learning rate | Size of each update | Too high creates artifacts; too low learns very little |
| Training steps / epochs | How long the dataset is repeated | Late checkpoints lose flexibility or copy backgrounds |
| Resolution and buckets | What spatial detail is visible | Cropped faces, stretched bodies, or lost full-body detail |
| Captions and trigger token | What is identity versus controllable context | Clothes or locations become fused to the person |
| Validation prompt and seed | A comparable checkpoint test | No evidence that training is improving |
There is no honest universal setting such as “1,500 steps always works.” Dataset size, rank, target modules, caption quality, resolution, and model architecture interact. Save checkpoints and compare them with a fixed validation suite.
For models supported by Hugging Face, the Diffusers training overview links maintained text-to-image and DreamBooth LoRA scripts. Do not assume a command written for SD 1.5 or SDXL is automatically valid for Z-Image.
8. Validate before activation
Do not approve a LoRA because one close-up looks good. Use a fixed matrix:
| Test | Keep fixed | Change | Pass condition |
|---|---|---|---|
| Expression | Identity, clothes, frame | Calm / laughing / determined | Same person, no frozen expression |
| Lighting | Identity, pose, frame | Window / neon / sunset | Skin tone and face geometry survive |
| Camera | Identity, outfit, setting | Close / half-body / full-body | Identity holds at distance |
| Wardrobe | Identity, face, light | Casual / formal / fantasy | Clothes change without changing the person |
| Background | Identity, expression, outfit | Home / street / landscape | Training backgrounds do not leak |
Use the same seed when comparing LoRA weights so the weight is the main changed variable.
Elyvie generates a controlled four-image A/B set at 0.65, 0.70, 0.75, and 0.80 LoRA weight. The same prompt and seed are used for every candidate. Each output is scored for identity and realism. When scores are close, the lower passing weight wins because it usually preserves more of the base model’s flexibility.
The correct weight is not necessarily 1.0. For one character it may be 0.65; another may need 0.80. Test rather than guess.
9. Diagnose the failure pattern
| Symptom | Likely cause | Next test |
|---|---|---|
| Face changes between scenes | Weak or contradictory anchors | Remove outlier anchors and retest neutral portraits |
| Face is right but every outfit repeats | Captions or dataset fused clothes to identity | Add wardrobe variation and caption it explicitly |
| Close-ups work, full-body shots fail | Too little scale variation | Add full-body and environmental training images |
| Skin looks waxy or over-retouched | Filtered source images or excessive adapter strength | Replace beauty-filtered images and lower the weight |
| Outputs copy training backgrounds | Duplicate scenes or missing background captions | Diversify locations and describe them in captions |
| Expressions barely change | Overtraining or weight too high | Compare an earlier checkpoint and lower weights |
| Adapter cannot be loaded | Wrong base family, format, ID, or missing file | Verify checkpoint compatibility and the LoRA catalog |
Change one variable per test. Rebuilding the dataset, changing the prompt, switching the base model, and raising the weight at once destroys the evidence.
10. What Elyvie automates, and what it does not
The no-signup free AI image generator is prompt-only. It does not upload references or train a LoRA.
Elyvie’s controlled character workflow automates:
- fictional-adult and image-rights checks;
- 4–5 identity-anchor selection;
- 20 varied scene candidates;
- identity, realism, duplicate, and safety review;
- a 15–20 image approved training manifest;
- Z-Image base-model training;
- a validation render;
- four-weight A/B testing before activation.
It currently accepts fictional character training sets, not unapproved real-person replicas. Training access is separate from the free public preview.
11. How I rent a GPU without making the rental the source of truth
I do not need to own a high-end GPU to own the character pipeline. I treat the rented GPU as disposable compute and keep the durable control plane in Elyvie.
The boundary looks like this:
Elyvie app → authenticated worker API → pinned Z-Image Base + selected LoRA → private result storage
The web app owns character records, permissions, job state, and final media. The GPU worker owns CUDA execution, model loading, training, and inference. A rental can be replaced without changing the public application contract.
Choosing a rental
For Elyvie’s current Z-Image Base and LoRA path, I target a 32 GB-class GPU rather than selecting by GPU name alone. A listing is acceptable only after checking:
- Verified or Secure Cloud status for production-sensitive work;
- reliability history and maximum rental duration;
- enough VRAM for the actual trainer, not just inference;
- disk capacity for model weights, package caches, dataset, checkpoints, and temporary files;
- upload and download bandwidth prices, not only Mbps;
- enough open ports for SSH and the authenticated worker;
- a region that keeps application-to-worker latency reasonable.
The Vast.ai instance guide defines reliability as historical uptime and health, exposes maximum duration, and separates GPU, storage, and bandwidth prices. A “verified” label is useful evidence, not a guarantee. I still run admission tests.
Disk should be planned before renting because Vast container storage cannot be resized later. My rule is to estimate the fully staged footprint and request about 2× headroom. If models, caches, trainer environment, dataset, and checkpoints can occupy 90 GB, a 100 GB disk is not a safe 90 GB disk.
The first ten minutes are an admission test
I do not spend an hour debugging a rental before deciding whether it is acceptable. A minimal preflight is:
nvidia-smi
df -h /workspace
curl -fsS "$WORKER_URL/health"
curl -fsS -H "Authorization: Bearer $API_TOKEN" "$WORKER_URL/v1/loras"
curl -fsS -H "Authorization: Bearer $API_TOKEN" "$WORKER_URL/v1/training-jobs"
Then I require:
- the expected GPU and VRAM are visible;
- the pinned base model reports ready;
- the LoRA catalog and training endpoints exist, not HTTP 404;
- an ordinary base-model render succeeds;
- a known adapter loads and produces one real image;
- the adapter filename, checksum, model ID, and generated image are recorded.
“Container running” is not the same as “training-capable worker.” I learned to verify the application capability, not the marketplace status badge.
Calculate the run, not just the hourly sticker price
Vast is a marketplace, so rates change. Its official pricing documentation says the bill combines compute, storage, and bandwidth, with compute billed by actual usage while storage continues as long as the instance exists.
Use:
Estimated run cost = GPU hourly rate × running hours + storage charge + bandwidth charge
For an illustrative offer at $0.35/hour:
| Phase | Time |
|---|---|
| Provision and admission test | 20 minutes |
| Dataset sync and environment warm-up | 20 minutes |
| Training and checkpoints | 70 minutes |
| Validation, A/B renders, and backup | 20 minutes |
| Total | 130 minutes = 2.17 hours |
Compute would be about $0.76 before storage and bandwidth: 2.17 × $0.35. If debugging stretches the session to four hours, compute becomes $1.40. The important insight is that GPU cost can be small while bad operational discipline is expensive. A cheap unreliable host that consumes two hours of attention is not cheap.
Stop, back up, then destroy
On Vast, stopping preserves container data but storage billing continues; destroying removes container storage permanently. The storage documentation also explains that Vast volumes survive instance deletion but remain tied to one physical host. A local volume is convenient persistence, not an off-site backup.
Before destroying a rental I export:
- the final
.safetensorsadapter and SHA-256 checksum; - dataset manifest and every accepted image hash;
- captions and trigger word;
- exact base-model ID and revision;
- trainer config, package versions, and checkpoint chosen;
- validation prompts, seeds, score sheet, and example outputs.
I copy these to storage outside the rented host. Vast supports Cloud Sync and standard data-movement methods, but the durable rule is provider-independent: a character does not exist safely until it can be rebuilt on another machine.
For sensitive material, use the smallest possible credentials and data scope. Vast’s instance-security notes explain that community hosts can technically access files on their machines; verified datacenters, encryption, private object storage, and fictional training data reduce the exposure.
12. Keep a reproducible character record
Store:
- identity sheet version;
- exact base model and revision;
- training tool and configuration;
- approved dataset manifest and captions;
- LoRA ID, adapter filename, trigger word, and active weight;
- reference rights and fictional-source attestation;
- fixed validation prompts and seeds;
- checkpoint comparisons, failures, and activation decision.
Keep the dataset and adapter outside an ephemeral GPU disk. A rented machine can disappear; the model file, manifest, captions, and configuration are the parts you need to reproduce the character.
A practical end-to-end workflow
- Draft the identity sheet.
- Generate three neutral portraits.
- Prove that the prompt-only identity is worth keeping.
- Select 4–5 clean, non-duplicate identity anchors.
- Build 15–20 varied and captioned training images.
- Rent a verified GPU with sufficient VRAM, disk headroom, duration, and acceptable bandwidth pricing.
- Reject the rental unless health, LoRA catalog, training, base render, and adapter canaries pass.
- Train against the exact production base model.
- Compare checkpoints on one fixed validation suite.
- A/B test several inference weights with the same prompt and seed.
- Activate only after identity and flexibility both pass.
- Back up the adapter, manifest, captions, configuration, checksums, and validation evidence before destroying the rental.
Frequently asked questions
How many images do I need for a character LoRA?
It depends on the model and dataset quality. Elyvie starts from 4–5 identity anchors, generates 20 varied candidates, and requires at least 15 to pass quality control before training. Fifteen diverse, sharp images are more useful than fifty near-duplicates.
Can a LoRA work with any image model?
No. A LoRA depends on the architecture and base checkpoint it was trained against. Verify the exact base family and loader before training.
Is a fixed seed enough to keep a character consistent?
No. A seed is useful for controlled comparisons, but identity can change when the prompt, model, dimensions, sampler, or adapter changes.
What LoRA weight should I use?
Test several weights with the same prompt and seed. Elyvie currently compares 0.65, 0.70, 0.75, and 0.80, then prefers the lowest weight that passes identity and realism checks.
Does Elyvie’s free image generator train LoRAs?
No. The free public generator is a prompt-only exploration tool. LoRA training belongs to a separate controlled fictional-character workflow.
Do I need to own a GPU to train a character LoRA?
No. A rented GPU is enough if the worker is reproducible and the dataset, adapter, configuration, and validation evidence are backed up outside the rental. Treat the machine as replaceable compute.
Why not use only a closed image API?
A closed API is excellent for early exploration. Elyvie uses open weights for durable characters because it needs to pin a base revision, train and load its own adapters, control inference parameters, move between GPU suppliers, and reproduce an older character version.
This workflow was verified against Elyvie’s implementation and the official Z-Image and Vast.ai documentation on July 30, 2026.
Start by testing your identity prompt in Elyvie’s free AI character generator →